How to Fix 'RuntimeError: element 0 of tensors does not require grad and does not have a grad_fn' in PyTorch on Linux
Start with the tensor passed to backward
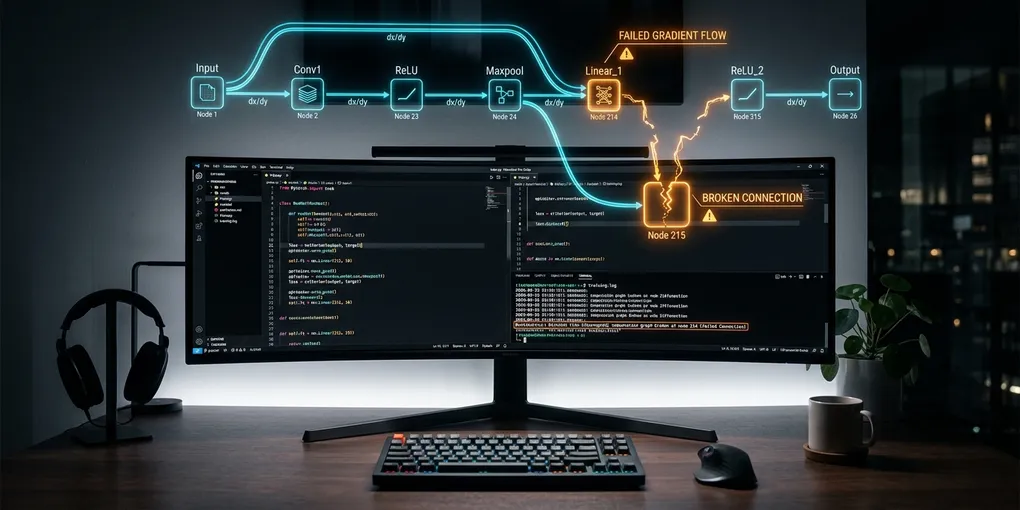
This error can occur when the loss does not track gradients. It does not, by itself, identify the operation or configuration responsible for the missing path. The Linux environment in the title is not enough to diagnose the problem; begin with the actual tensor passed to backward and the parameters the training step is supposed to affect.
The supplied PyTorch leaf and non-leaf tutorial illustrates the error in a small network when the loss is not tracking gradients. Its tracked example connects gradient-enabled weights and bias through an affine operation, ReLU, and mean-squared-error loss. That example provides a useful investigation pattern: trace the specific path from intended parameters to the loss, instead of assuming that the error identifies the faulty line.
The excerpt is labeled PyTorch v2.15.0+cu132. Treat its example as evidence for that documented context, not as a version-independent specification for every model, operation, or training framework. Record the installed release and consult its matching documentation before changing behavior. The excerpt does not establish a complete set of release-specific rules for gradient modes, backward arguments, optimizers, or discrete operations.
Choose the next check
Use the following decision tree as an investigation checklist. Attribute names are inspection targets; consult the documentation for the pinned release and framework before relying on their exact semantics.
- Is this the training loss you intended to differentiate? Follow its construction back to the prediction and identify the batch and branch that produced it. If a metric or a newly constructed value was passed instead, inspect where it diverged from the intended objective.
- Does the loss report that it requires gradients? If not, compare the actual path with the tutorial’s tracked example. Inspect the parameters and operations involved, then investigate where tracking first differs from what the pinned release’s documentation says to expect.
- Does the loss report a recorded operation? If it does, investigate whether that operation belongs to the path from the intended parameters. Evidence that some computation was recorded does not establish that it connects the loss to every parameter you meant to train.
- Does the loss have the shape expected by your backward call? Check the installed release’s backward documentation for its requirements, including any required gradient argument or reduction. The supplied excerpt demonstrates a scalar loss; it does not establish the general shape rules.
- Are the intended parameters trainable and selected by the training setup? Inspect the actual parameter objects and the optimizer configuration. Use the pinned optimizer documentation to determine how changes to the model or trainable selection affect the optimizer.
Stop at the earliest mismatch you can explain. After a change, use a fresh training step under controlled debugging conditions and check the relevant observations again. A different exception or an unexpected gradient deserves its own investigation; this error message is not proof that every later step will succeed.
Trace the path without relying on a canned diagnostic
Before making changes, identify the model component expected to learn, the prediction it produces, and the expression that constructs the loss. Record the names and identities of the relevant parameters from the instantiated model. A component name copied from another architecture is not evidence that the same component exists in yours.
For each boundary between prediction and loss, inspect what the code actually does. In particular, flag explicit detachment, conversion outside the tensor computation, reconstruction of a value, and contexts that may alter gradient recording. These are places to investigate, not a claim that any one of them caused your error. Check the relevant API behavior against documentation for the installed release.
If you plan to inspect gradients during a debugging step, first determine how your training loop handles existing gradients and accumulation. Clearing or altering them can change the next update. Use a disposable step or preserve the state needed by your workflow, and consult the release documentation for how to interpret gradient fields on the tensors you inspect. A gradient observation should be tied to the exact forward path and parameters used in that step.
This page intentionally provides no runnable diagnostic: the supplied evidence does not validate a complete example in a reproducible environment. In particular, do not infer from a printed attribute alone that a subsequent backward pass or optimizer update will have the intended effect.
Check freezing, adapters, and optimizer setup
If the intended component is frozen or was changed after the optimizer was created, inspect both the model’s parameter configuration and the optimizer’s actual parameter groups. Compare objects, not just similar-looking names. Before adding parameters or rebuilding an optimizer, verify the documented procedure and determine how your checkpoint and optimizer state should be handled for the pinned release.
For adapter-based training, first inspect the instantiated adapter and its trainable parameters. The PEFT documentation describes methods that adapt pretrained models by fine-tuning a small number of additional parameters and notes integration with Transformers, Diffusers, and Accelerate. It does not establish which module names, targets, or optimizer settings are correct for your particular model. Pin the PEFT release as well as PyTorch, and consult the documentation for the chosen adapter method.
Review classification and discrete decisions separately
If the loss path includes class selection, rounding, a comparison, or a mask, identify whether the training objective needs a gradient through the decision itself or through values used elsewhere. Then check the derivative behavior, accepted inputs, shapes, and target types in the pinned release’s documentation for the exact operations and loss.
Do not substitute a different loss or a relaxed decision merely to silence this exception. Such a change can alter the objective, and the supplied excerpts do not verify a release-specific classification recipe or the behavior of these discrete operations. Validate any proposed replacement against both its documentation and the mathematical objective of the application.
Primary sources and validation boundary
- PyTorch: Understanding leaf and non-leaf tensors illustrates a tracked parameter-to-loss graph and the error when the example’s loss does not track gradients.
- Hugging Face PEFT documentation describes parameter-efficient adaptation and integrations with other model libraries.
The supplied excerpts do not validate a complete diagnostic, a general backward shape rule, optimizer modification procedures, gradient-mode behavior, or a classification or discrete-operation remedy. Verify those details against the documentation for the exact installed releases and validate changes in your own controlled environment. No command, test, training run, GPU execution, API call, benchmark, or numerical result was independently executed for this correction.
The supplied source excerpts were reviewed for this correction on November 13, 2026. Current documentation does not establish what was available on the original publication date.