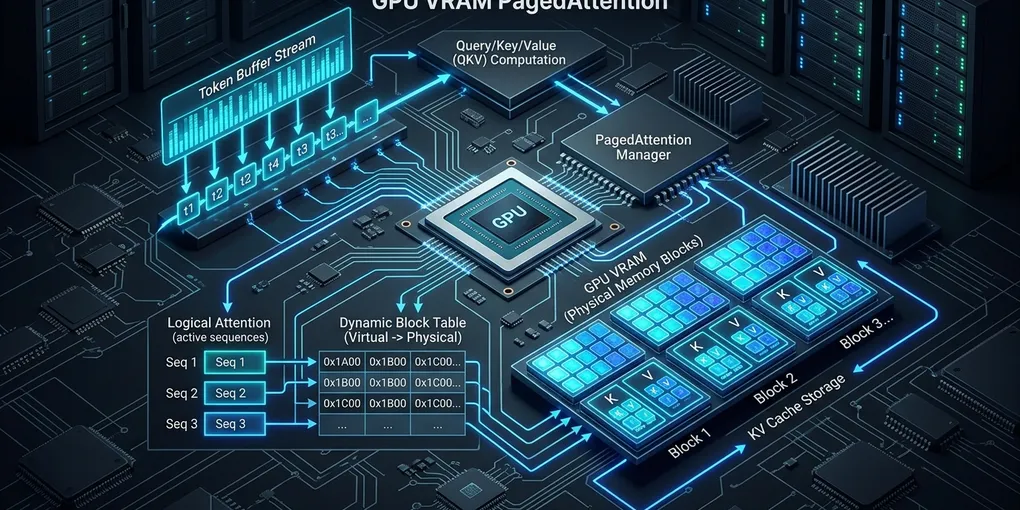
How to Fix KV Cache Exhaustion and Request Preemption in vLLM on Linux
Diagnose vLLM V1 KV-cache preemption without outdated CPU swapping advice
A vLLM server may accept requests yet slow down abruptly when several agent conversations compete for KV-cache space. Those slowdowns can come from long prompts, concurrency, insufficient memory for active sequences, or repeated recomputation after scheduler preemption. A preemption is not automatically a deadlock.
Technical correction, November 11, 2026: The original article recommended --swap-space 0, claimed that a fixed 12 GB CPU transfer always adds 750 ms, and described universal GPU-utilization and time-to-first-token thresholds. Those claims were either obsolete for vLLM V1 or lacked a measured environment. This revision distinguishes the removed legacy swap behavior from supported preemption/recomputation and provides a measurable diagnostic workflow. The first publication date remains unchanged.
The controlling references are the vLLM V1 user guide, scheduler optimization guide, serve CLI reference, and V1 metrics design.
1. Check the engine generation before changing a flag
Early vLLM implementations could swap some KV-cache blocks between GPU and CPU memory as part of request preemption. vLLM V1 removed that legacy GPU-to-CPU swap path. Current V1 uses a simpler scheduling and recomputation approach to handle preempted requests; older documentation about --swap-space is not an instruction for a current V1 installation.
This distinction does not mean all forms of KV offloading are impossible. Current vLLM has separately documented opt-in KV offloading configurations such as --kv-offloading-size and --kv-offloading-backend. Those features are not equivalent to the removed V0 request-preemption swap path, and enabling them without measuring the hardware is not a default fix.
Inspect the installed build and its actual CLI options:
python -m pip show vllm
vllm serve --help | grep -E 'max-num-seqs|max-model-len|gpu-memory-utilization|kv-offloading|enable-prefix-caching'
If the help output differs from this article, use the behavior of your pinned version. Do not try to fix preemption with an option that the installed CLI no longer recognizes.
2. Separate capacity, scheduling and observed symptoms
Before tuning, classify the problem:
- Startup says KV capacity cannot fit the requested context length: Check the model, maximum sequence length, quantization, actual free GPU memory and startup cache-capacity log. This is not evidence of a CPU swapping deadlock.
- The server starts, but concurrent requests wait and preemption warnings accumulate: Inspect running/waiting requests, active token budgets and the V1 scheduler’s preemption/recomputation behavior.
- Prompt latency is high without preemptions: Examine prompt length, prefix-cache reuse, prefill throughput and other model/kernel bottlenecks before blaming KV capacity.
- An unrelated CUDA out-of-memory error occurs: Separate transient graph-capture or extension allocations from the KV-cache budget.
For related startup failures, see our vLLM out-of-memory diagnostic guide. Each case calls for a different test.
3. Use controlled concurrency instead of a universal “optimized” command
In V1, --max-num-seqs limits the number of sequences processed in a scheduler iteration. --max-num-batched-tokens bounds the number of tokens processed in an iteration. These are scheduler limits, not guarantees that any given amount of GPU memory will always be sufficient.
Before touching a live instance, use a version-aware configuration checklist, not a portable GPU launch recipe:
| Setting | Illustrative comparison value, not a prescription | Evidence required |
|---|---|---|
--max-model-len |
8192 tokens | Real application context requirement and model compatibility |
--max-num-seqs |
8 sequences | Offered load, throughput, queue wait and preemption counts |
--gpu-memory-utilization |
0.85 | Actual available GPU memory, startup cache estimate and concurrent processes |
--max-num-batched-tokens |
Select from installed CLI | Actual prompt lengths, latency and prefill budget |
| Network and authorization | Local loopback for development | Authentication and separate internal worker-port isolation |
These numbers are illustrative inputs for a controlled comparison. There is intentionally no copy-paste vllm serve command: the named model, runtime version and GPU resources were not independently tested by this publication. Check the current CLI in your installed environment before planning an authorized test.
It does not claim to eliminate preemption on all GPUs. 0.85 is a comparison setting, not a universally optimal reserve. Increasing utilization can leave less headroom for other processes and memory spikes; decreasing max-num-seqs may reduce active contention but can also increase queueing. Measure both sides of the trade-off.
V1 enables chunked prefill by default when supported. Prefix caching is also part of its normal V1 feature set. Neither should be described as a magic switch that makes a reused prefix consume zero GPU memory. A cache hit can save prefill computation, but KV blocks still occupy capacity, and hit rates depend on request prefixes and eviction behavior.
Avoid hard-coded prescriptions such as --block-size 16 or changing a 16-token block to 32 tokens for every Hopper server. The effective layout and accepted values are model- and backend-dependent.
Offline capacity math cannot prove runtime preemption
We publish an offline, inspectable capacity calculator with a downloadable synthetic GQA model config. The planner is useful before a live workload to make memory assumptions visible. Its formula assumes a single-GPU, full-attention MHA/GQA deployment. The input validator rejects selected recognizable unsupported metadata, including qwen3_5/qwen3.8 model types, declared MLA ranks, nonzero sliding-window settings or nested multimodal configuration. It cannot detect every hybrid architecture or verify actual GPU sharding; the reader must independently establish the architecture and runtime topology before trusting a numerical result.
Run python3 kv_cache_capacity_audit.py --self-test after reviewing and downloading the source. A dedicated eight-test regression suite and the self-test were executed on the synthetic fixture without a CUDA device or network calls from the calculator. The fixture’s 24 GiB / BF16 / 8,192-token / 64-layer GQA example consumes 2 GiB per sequence for KV data. With deliberately hypothetical weight and runtime reservations (17.1 GiB and 1.4 GiB), the arithmetic admits one sequence under a 90% utilization budget but rejects two; this is not observed vLLM behavior.
| What the offline calculation says | What you must check in the live vLLM service |
|---|---|
| A planned sequence exceeds the declared KV budget | Inspect the real model’s startup KV capacity and supported context setting |
| A planned sequence appears to fit | Still measure actual running/waiting requests, KV utilization, and preemption/recomputation |
| Reducing requested sequences changes the arithmetic | Validate the same offered load: queueing and throughput may worsen |
| The tool detects unsupported architecture metadata | Treat rejection as a stop signal; undetected hybrid or sharded configurations still require manual verification |
The calculator models declared capacity, while the metrics and warning counter below capture runtime scheduling. Combining them helps distinguish a bad planning assumption from actual preemption. It cannot establish that a configuration will be accepted, faster, or numerically accurate.
4. Inspect metrics and actual preemption warnings
The server’s local OpenAI-compatible API may expose a Prometheus-compatible /metrics endpoint. The exact metric set depends on the vLLM release.
curl --max-time 4 -fsS http://127.0.0.1:8000/metrics \
  | grep -E 'vllm:(num_requests_running|num_requests_waiting|kv_cache_usage_perc|prefix_cache_hits)' \
  | head -35
For example, vLLM’s V1 metrics documentation describes vllm:kv_cache_usage_perc and request-count metrics. If this command finds no match, first inspect the full metrics output and your version’s naming. A missing line is not evidence of zero cache use or no preemptions.
The optimization guide also describes an engine warning field named total_cumulative_preemption_cnt. Track the change in this counter over a defined period while recording request arrivals, prompt/output lengths, and the model configuration. Do not confuse a lifetime cumulative counter with a per-second rate.
Use paired measurements: cache usage and preemption events, plus request queueing and completion. A cache-usage percentage alone does not establish that the scheduler is thrashing.
A small diagnostic decision table
- Repeated preemption warnings under a fixed workload: Compare one run with a lower
--max-num-seqs; record completion rate and latency, including queue time. - KV capacity too low at startup: Reduce
--max-model-lenif the application allows it, or use a model/precision that genuinely fits. Do not pretend that lowering context magically shrinks model weights. - Large shared prefixes with low reuse: Inspect whether the requests are truly identical in their cached prefixes and whether the feature is supported by the deployed model. Prefix caching is not a universal zero-latency guarantee.
- The GPU is nearly full before startup: Identify competing processes and ownership. Do not kill shared GPU users automatically.
5. Record a defensible before/after result
To evaluate a configuration change, hold the model, checkpoint revision, GPU, driver, vLLM release, request mixture and offered load constant. Record:
- Startup success and the reported KV-cache capacity.
- Number of accepted/completed/failed requests, not just the largest prompt accepted.
- Change in preemption warnings or counters.
- End-to-end latency, time-to-first-token and time between generated tokens, measured with a stated method.
- Queueing and throughput, so a lower preemption count caused by rejecting or serializing all work is not mistaken for a performance win.
Do not attribute a fixed 750 ms PCIe transfer penalty, an inevitable 5-second TTFT or a particular 15% GPU utilization to all systems. Those require an actual trace and hardware-specific experiment. This article supplies a measurement plan, not fabricated results.
6. What this guide establishes
The current vLLM V1 documentation supports the core distinction: old swap-based preemption was removed, while KV-cache limits and recomputation remain operational issues. It does not establish that the commands above were run successfully on a particular GPU or that the settings are universally optimal.
Use a bounded staging workload under your own authorization. Keep the previous known-good launch configuration so it can be restored if the new one fails.
Primary sources
- vLLM V1 design and removed legacy features
- Official vLLM V1 optimization and preemption guidance
- Current
vllm servearguments - vLLM V1 metrics reference (metric names vary by version)
- Automatic prefix caching behavior
Revised November 12, 2026. Offline synthetic capacity tests were executed, but no production GPU benchmark or measured vLLM preemption experiment was conducted. Available flags and metrics can change between releases.