How to Fix Malformed Tool Calls and JSON Parse Errors in Local LLMs on Linux
A malformed tool call can originate in the model output, the serving layer, a proxy, or the client’s interpretation of the response. An empty call list can also be a valid result when the request permits the model to answer without using a tool. Start by identifying which of those outcomes occurred; do not dispatch anything merely because generated text resembles a function call.
The vLLM documentation lists structured output generation, tool-calling parsers, and an OpenAI-compatible API server as capabilities. Its landing page is a developer preview and points readers to stable-release documentation. That distinction matters: it does not establish which parser, launch option, model template, or request mode works in a particular installed release.
Triage the response first
Capture a sanitized request and response at each boundary: client to proxy, proxy to server, and server back to client. Preserve the response structure, completion status, tool-call fields, and argument bytes. Remove credentials and sensitive user data from diagnostic records, and restrict access to any remaining operational data.
Use this decision tree:
- Did the request complete successfully? If not, investigate the transport, server error, or incomplete generation before interpreting tool fields.
- Is the response complete and valid for the endpoint’s documented format? If it is truncated or structurally invalid, record the failure and stop. For streaming, assemble the response according to the pinned endpoint’s documentation before validation.
- Are there tool calls? If none are present, check the requested tool-choice mode and the response content. A no-tool answer may be valid; if the workflow requires a call, classify it as an unmet workflow requirement rather than inventing one.
- Are calls present but arguments invalid? Treat parsing, schema validation, and authorization as separate checks. A successful JSON parse does not make a call safe or meaningful.
- Does a proxy change the request or response? Compare sanitized records on both sides. Investigate a demonstrated difference using that proxy’s documentation for the installed version.
Raw text that looks like a tool call is evidence for diagnosis, not proof of a parser defect. Likewise, an empty object may be valid for a tool with no required arguments or invalid for a different schema. Inspect the actual contract before assigning a cause.
Pin the behavior before changing configuration
Record the server and client versions, container image digest or package build, model and tokenizer revisions, chat template, request parameters, tool schemas, and any proxy version. Keep the original settings with the incident record so a proposed change can be compared against the same request.
For the exact serving release:
- Find its official versioned documentation for the endpoint, model, template, tool parser, and tool-choice modes. Confirm that any proposed option exists in that release and applies to that combination.
- Check the documented conditions for structured or constrained decoding: the request form, supported schema features, backend, and whether the constraint applies to tool arguments in that mode. Do not infer a schema guarantee from the presence of a backend alone.
- Verify the model’s tool-call format and any parser mapping in documentation or examples for the pinned revisions. A mapping for one model family, server, or release is not evidence for another.
- Change one variable at a time in an isolated test. Compare the original request with the changed configuration, including no-tool and malformed-output cases.
The SGLang repository identifies it as a separate inference framework and directs readers to its quickstart and model-and-hardware cookbook. Use its own release-specific guidance when investigating SGLang; vLLM options are not established as SGLang options by these sources. Apply the same evidence standard to Ollama and LiteLLM: consult their official documentation for the installed versions before changing a template, proxy setting, or release.
Validate before dispatch
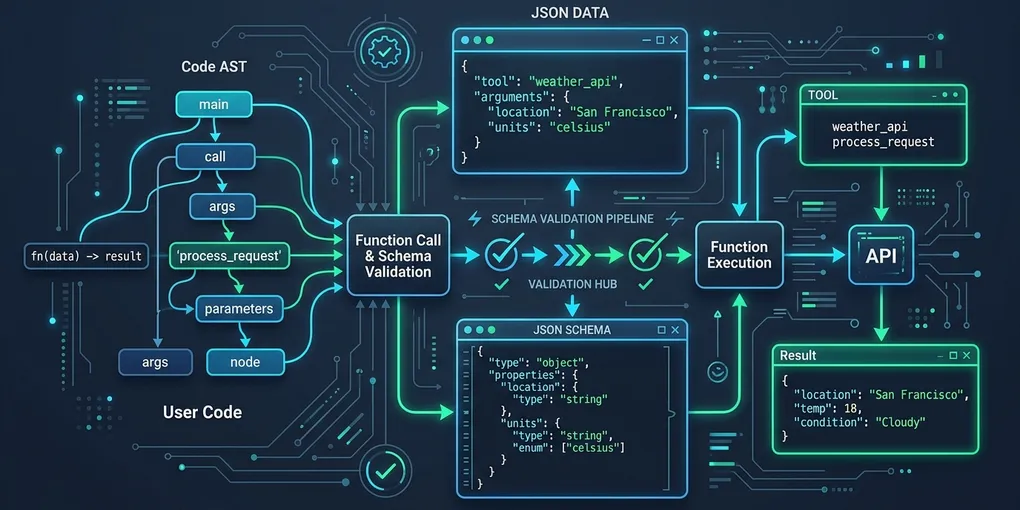
Treat both native tool-call fields and any recovered text as untrusted. A safe processing boundary should:
- Enforce limits on response size, number of calls, argument size, nesting, and processing time before parsing.
- Accept only the documented response envelope. If a deployment explicitly supports a raw-text fallback, use a format-aware parser for that exact, versioned format; reject ambiguous framing, incomplete input, trailing data, and malformed JSON. Do not split text on
}{, strip tags with a generic regex, or accept Python literals as JSON. - Require a tool name from the request’s authorized allowlist. Reject unknown names and calls that the current user or workflow is not authorized to invoke.
- Parse arguments as strict JSON where the contract requires JSON, then validate them against the exact schema sent for that tool. Check required fields, types, allowed values, extra fields, and application-specific bounds. Make coercion an explicit policy rather than silently changing types.
- Apply tool-specific authorization and safety checks to the validated values before execution. Parsing and schema validity do not authorize a database query, file access, network request, or other side effect.
- Reject invalid calls without dispatching them. Return a controlled error or request a new response under a bounded retry policy; log the failure category without exposing secrets or sensitive arguments.
If the exact raw format is not documented and tested, disable recovery and retain the content only as diagnostic evidence. Never execute generated text as code.
Verify a change without assuming a call
Build a test fixture around a non-destructive tool and a pinned schema. Record the versions and request alongside the sanitized response. For a request that permits automatic choice, distinguish a valid no-tool response from a valid call; neither should be reported as the other.
For each returned call, check that the list is nonempty before indexing it, the name is authorized, arguments parse completely, and the parsed value passes the intended schema and application checks. Test rejection of unknown names, invalid JSON, missing required fields, oversized input, truncated streams, and multiple calls. Include a string containing }{ to ensure framing logic does not corrupt valid content.
A passing validation means only that the recorded cases passed on the recorded configuration. Repeat the checks after changing the model revision, template, serving release, client, or proxy. The Hugging Face Hub library documentation provides version selection and describes its role in accessing Hub files; record the actual model artifacts and revisions used rather than assuming a model name alone identifies the deployed files.
Primary sources and validation boundary
- vLLM documentation describes its listed serving capabilities and identifies the landing page as developer-preview documentation.
- SGLang repository describes the framework and points to its quickstart and cookbook.
- Hugging Face Hub library documentation describes the Hub client and exposes versioned documentation.
No commands, configurations, model/parser pairings, or runtime outcomes have been independently executed or verified for this article. The supplied source excerpts do not establish a release-specific fix or prove what documentation said on a historical date. Source-review notice: November 13, 2026; the review is limited to the supplied excerpts.