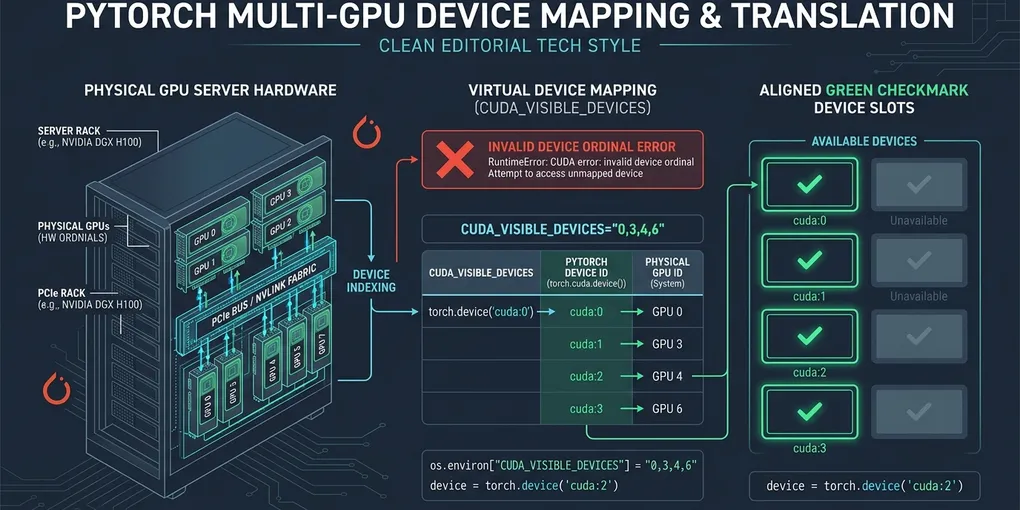
How to Fix 'RuntimeError: CUDA error: invalid device ordinal' in PyTorch on Linux
RuntimeError: CUDA error: invalid device ordinal is a reason to examine the device index requested by the failing process and how the application chose it. Start in the same container, scheduler allocation, Python environment, and launcher context as the failure. A host inventory is useful context, but it does not by itself establish what the failing application can use.
The supplied sources support narrow claims about two PyTorch 2.15 APIs. They do not establish CUDA masking rules, container enumeration, initialization timing, or distributed launcher mappings. The checks below are an investigation plan, not a verified recipe for any particular deployment.
Choose a diagnostic path
Record the requested device and the complete exception, then work through these branches:
- CUDA is unavailable to the failing process. Investigate the installed PyTorch build, driver access, allocation, container setup, and release compatibility. If the workload permits CPU execution, apply its explicit CPU policy; if it requires a GPU, report the failure clearly.
- A device count is available, and the requested index is outside the range documented for the installed release. Trace where that index came from: application configuration, a command-line argument, or launcher-provided information. Correct the source only after checking the relevant release documentation.
- The requested index appears valid under the installed release’s rules. Preserve the full exception and identify the operation that reported it. Investigate initialization and device access as well as index selection. A count alone does not prove that an allocation or workload will succeed.
- Only a container or distributed run fails. Collect the same observations from the failing process in that context. Compare them with the intended allocation and consult the documentation for the exact container runtime, launcher, and framework versions.
Establish what the application requested
The PyTorch 2.15 torch.cuda.device_count() reference states that the function returns the number of GPUs available. Its excerpt does not define how a scheduler, container, or visibility setting affects enumeration. Apply that API statement to an installed release only after checking its corresponding documentation.
For the failing process, record:
- PyTorch version and build, driver version, and relevant CUDA version information.
- CUDA availability, the reported device count, the requested index, and the exact operation associated with the exception.
- Relevant launch settings and their source, without collecting credentials or unrelated environment variables.
- Container, scheduler, and launcher versions and configuration, where applicable.
Keep the host inventory as a separate record. If installed tools expose GPU UUIDs or PCI bus IDs, record those identifiers alongside any device numbers. Consult the installed tools’ documentation before using them to correlate an application device with hardware; the supplied excerpts do not establish that mapping.
Check device selection and fallback policy
The PyTorch 2.15 torch.cuda.set_device() reference says the function sets the current device, discourages its use in favor of device, and says CUDA_VISIBLE_DEVICES is preferable in most cases. It also says a negative argument makes the function a no-op. That last detail matters when reviewing validation: passing a negative value is not, by itself, evidence that selection failed.
For the installed PyTorch release, verify the documented device-index rules and the intended API before changing code. A bounded review should cover these decisions:
- If CPU execution is allowed, make that an explicit outcome and avoid calling CUDA device-property APIs for the CPU path.
- If a GPU is required, reject missing or invalid selection information with a message that includes the request and the observed count.
- If a fallback is allowed, define which fallback is authorized and report when it is used. Do not silently substitute a different device for a configuration error.
- After selection, treat a small allocation as a separate check. Report an allocation failure instead of treating selection or a device count as proof of readiness.
These are checks to perform in the target environment; no CPU or GPU branch has been exercised for this page.
Inspect launch settings and initialization
Record the relevant settings supplied to the failing process and identify where the application first performs CUDA-related work. If a setting or initialization order is suspected, consult the documentation for the pinned CUDA and PyTorch releases before proposing a change. Compare fresh process launches under controlled, otherwise equivalent conditions, recording both the settings and observations.
The set_device() excerpt mentions CUDA_VISIBLE_DEVICES, but it does not specify its masking semantics, when changes take effect, or how indices relate to host inventory numbers. Do not derive a mapping or a timing guarantee from that reference. The NVIDIA CUDA documentation hub lists the toolkit archive, release notes, programming guides, and runtime and driver API references; use those entry points to find and verify the applicable release-specific rules.
Containers and distributed workers
For a container-only failure, record the exact image, runtime and toolkit versions, launch configuration, and observations from the failing application process. Check the installed runtime’s documentation for its device-exposure syntax and the installed CUDA and PyTorch documentation for enumeration. Do not assume that a device number in a host inventory or a container device-node name identifies the application’s requested device.
For a distributed failure, collect a separate record for each affected worker: node identity, launcher and framework versions, any rank values actually supplied, reported device count, requested device, and exception. Then inspect the pinned launcher and framework documentation for the variables and placement contract that apply to that launch. A global rank, a local rank, and a requested device index are different pieces of information; do not substitute one for another without a documented contract.
If the application requires a launcher-provided value and it is absent, report the missing value and launch context. Before adding manual selection, check whether the framework already has a documented placement mechanism and how the proposed setting interacts with it. The supplied sources do not establish any worker-to-device assignment rule.
Validate the result
A useful audit records each attempted check and its actual outcome. If a required allocation fails, report failure; if CPU execution is an accepted outcome, report it separately. If an out-of-range selection is deliberately tested, record unexpected success as a finding requiring investigation rather than printing unconditional success.
Even successful allocations establish only the checks actually attempted. They do not establish that a training job will complete or that worker placement matches the intended hardware allocation. Verify those separately using the applicable release documentation and observations from the target environment.
Primary sources and validation boundary
- PyTorch 2.15:
torch.cuda.device_count()documents the available-GPU count returned by that API. - PyTorch 2.15:
torch.cuda.set_device()documents current-device selection and the negative-argument no-op. - NVIDIA CUDA Toolkit documentation hub provides entry points to release-specific CUDA documentation; the supplied excerpt does not establish mapping or launcher behavior.
Validation boundary and source-review notice — November 13, 2026: This page relies on the supplied excerpts, which do not establish when the live sources were reviewed or what they said on a historical date. No command, source page, image, allocation, GPU workload, or distributed launch was independently checked for this article. Verify procedures and any executable commands against the primary documentation for the pinned releases and the target environment before production use.