vLLM v0.31 Preload and CUDA IPC: A Safer Zero-Copy Restart Guide
Technical correction, November 12, 2026: An older version of this guide claimed an always-three-second engine restart, asserted unrelated Python, CORS and KV-cache changes without a release-specific citation, and included an unauthenticated inference server listening on all network interfaces. Those claims and that exposed production recipe have been removed. The examples below are illustrative and version-sensitive, not measurements from a deployed model.
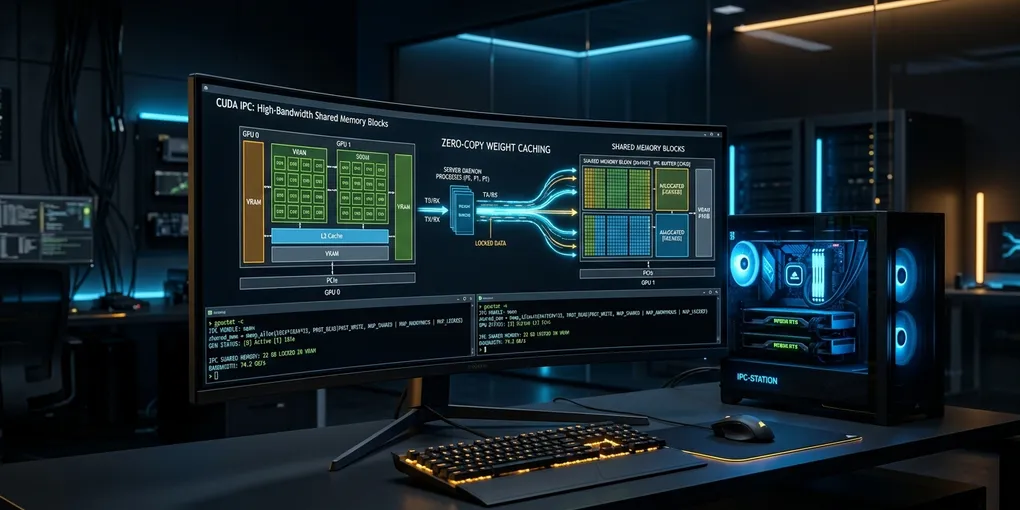
The vLLM v0.31 preload guide describes a weight-cache daemon that holds model weights in GPU memory while a serving engine can restart and attach to them through CUDA IPC. This can avoid repeating the weight-loading stage when the cache is compatible. It does not remove all server startup work, guarantee a given restart time or automatically secure a public inference endpoint.
What the preload daemon changes
For a compatible CUDA setup, vllm preload starts a weight-cache daemon for the selected model and its tensor-parallel ranks. When a vllm serve process uses --load-format ipc_cache, the serving process can access the compatible cached weights instead of loading the same weights again from storage.
The documented vLLM loader behavior includes several checks:
- The model configuration and cached-weight fingerprint must match what the serving engine expects.
- The daemon’s GPU identity must match the target GPU.
- In default
zero_copymode, the daemon needs to remain alive while the engine uses its allocations. - If the daemon is unavailable or the cache fingerprint does not match, the loader falls back to loading from disk by default. Therefore, choosing the
ipc_cacheformat does not guarantee zero disk reads for every restart. - The manual describes a
copymode with a different GPU-memory lifetime, and warns that sleep mode should not be combined with default zero-copy IPC allocations.
The improvement concerns model-weight loading, not automatic rollback of in-flight requests, permission checks or all other initialization overhead.
Inspect the environment before a first test
Use a dedicated, authorized Linux GPU host. Verify the installed Python environment, vLLM version, GPU count and model location:
python3 --version
python3 -m pip show vllm
nvidia-smi --query-gpu=index,name,memory.used,memory.total --format=csv
These commands read environment information; they do not start or modify services. Choose a model that is already available to the serving account, and verify it works without caching first.
Only after checking the versioned vLLM v0.31 CLI reference should you consider this two-process example in an isolated, approved environment:
# Terminal A: authorized local GPU host, model path reviewed by administrator
vllm preload --model /path/to/approved-model --tensor-parallel-size 1
# Terminal B: the same authorized host and model/configuration
vllm serve /path/to/approved-model \
--tensor-parallel-size 1 \
--load-format ipc_cache \
--host 127.0.0.1 \
--port 8000The model path is a placeholder, not a ready-to-run installed model. A GPU allocation in the daemon uses VRAM even when the HTTP engine is down. Other GPU jobs need headroom.
Why localhost? The API server can handle tool-connected or confidential inference workloads. The vLLM security documentation advises controlling access to privileged serving functions. Binding to loopback reduces accidental exposure in a demonstration. A real multi-user deployment needs an authorized network architecture, access control and reverse proxy or equivalent gateway rather than an unrestricted public listener.
Zero-copy is not a universal process-isolation guarantee
In the documented default mode, a daemon exports GPU memory handles and the engine maps them through CUDA IPC. This is local, specialized GPU memory sharing, not permission to let arbitrary users connect to the Unix socket.
The vLLM guide documents a per-user private socket directory by default. If you override socket_dir, ensure the daemon and serving process use matching settings and check filesystem ownership, permissions and lifecycle. Do not place the socket in a world-writable mount or change host permissions broadly to make a connection work.
Containerizing one or both processes introduces additional namespace, GPU-device and Unix-socket mount considerations. The Docker IPC mode documentation says that host IPC mode uses the host system IPC namespace rather than a private container namespace. This reduces IPC namespace separation and is not proof that the required socket is mounted or accessible; it is not a safe default workaround.
Do not assume the cache persists after the daemon exits. Losing its GPU allocations changes what a subsequent engine can map, and vLLM may load from disk depending on the loader’s fallback setting.
Avoid hard-coded systemd and startup promises
The previous article supplied two system-wide units, an external network bind, a fixed GPU allocation budget and a mandatory service restart sequence. That configuration depends on the exact Linux user, process manager, model size, driver, socket directory and availability requirements.
A production service design should answer the following questions before any systemd unit is enabled:
- Which user and permissions own the daemon and engine?
- Does the daemon’s configured socket directory match the engine loader’s directory?
- Are the daemon and engine version/model/rank settings identical where required?
- How does the engine handle a missing cache, fingerprint mismatch or daemon restart?
- Are the HTTP endpoint and management surfaces restricted to authorized clients?
- Is a model output health check available after each restart, rather than only a healthy PID?
- Can the rollout be reversed to the normal loading mode without exposing a service?
If you require multiple GPUs or nodes, review the vLLM preload documentation for tensor, data and expert parallelism. The versioned vLLM v0.31.0 guide states that pipeline parallelism is rejected when launching the preload daemon. Check the relevant version if moving to a newer release rather than extrapolating this restriction to every future version. CUDA IPC handles are node-local; deploying across nodes requires appropriately scoped local daemons rather than copying handles over a network.
Measure before promising a speedup
A convincing result should compare the same version, model weights, hardware, quantization and tensor-parallel configuration for the standard loader and an already-warmed weight daemon. Record model-first-token readiness, engine time-to-healthy, fallback events, daemon VRAM use and any additional warmup time.
The official feature guide discusses faster restarts, but this article provides no independently measured latency, 3-second SLA or PCIe traffic counter. Its diagrammatic premise is weight re-use, not a guarantee that every GPU initialization, cache warmup or safety step disappears.
Primary references
- vLLM v0.31.0 weight preload and CUDA IPC documentation
- vLLM v0.31.0 serve CLI network and loader flags
- Current vLLM preload lifecycle, fallback and cache mode
- vLLM serving security considerations
- Docker IPC namespace configuration
Editorial correction, November 12, 2026: Original publication date and URL preserved. This guide is documentation-based; no production inference system or repeatable startup-speed benchmark was executed as part of the correction.